AI Infrastructure

K-SMART AI SERVER

A GPU server powered by four NVIDIA RTX PRO 6000 Blackwell GPUs
AI infrastructure for education, research and cloud — from design through operation.

4GPURTX PRO 6000 Blackwell
384GBTotal GPU Memory
8PFLOPSAI Performance (FP8)
AI GPU SERVER MANUFACTURINGAI GPU Server ManufacturingRTX PRO 6000-based servers assembled and validated in Korea, with direct after-sales service.
Why K-SMART

From devices to servers,
one supplier for everything

AI infrastructure is more than a single server. The tablets students use, the software that runs the classroom, and the servers doing the computing behind them all have to work as one.
K-SMART supplies all three layers in-house and takes responsibility from installation to after-sales service through a single point of contact.

LAYER 01

Learning Devices

Smartphones and tablet PCs designed and produced for education environments.

  • 11" education tablet · 7 smartphone models
  • Built-in MDM · KC certified
  • All-in-one accessory package included
LAYER 02

Education Software

An integrated software layer covering classroom operation and assessment.

  • MDM — Unified remote device management
  • LMS — Learning management · Focus mode
  • AI Proctor — Online exam proctoring
LAYER 03

AI Infrastructure

The GPU server layer that powers the computing behind every service.

  • RTX PRO 6000 Blackwell 4-GPU server
  • Scales from 1 server to a 10-node cluster
  • Deployment · operation · maintenance, all in one

No need to manage multiple vendors. Procurement, deployment, training and after-sales service are all handled by K-SMART in one place.

Product

4-GPU AI Server

A rackmount server with a high-density configuration of data-center passive GPUs.
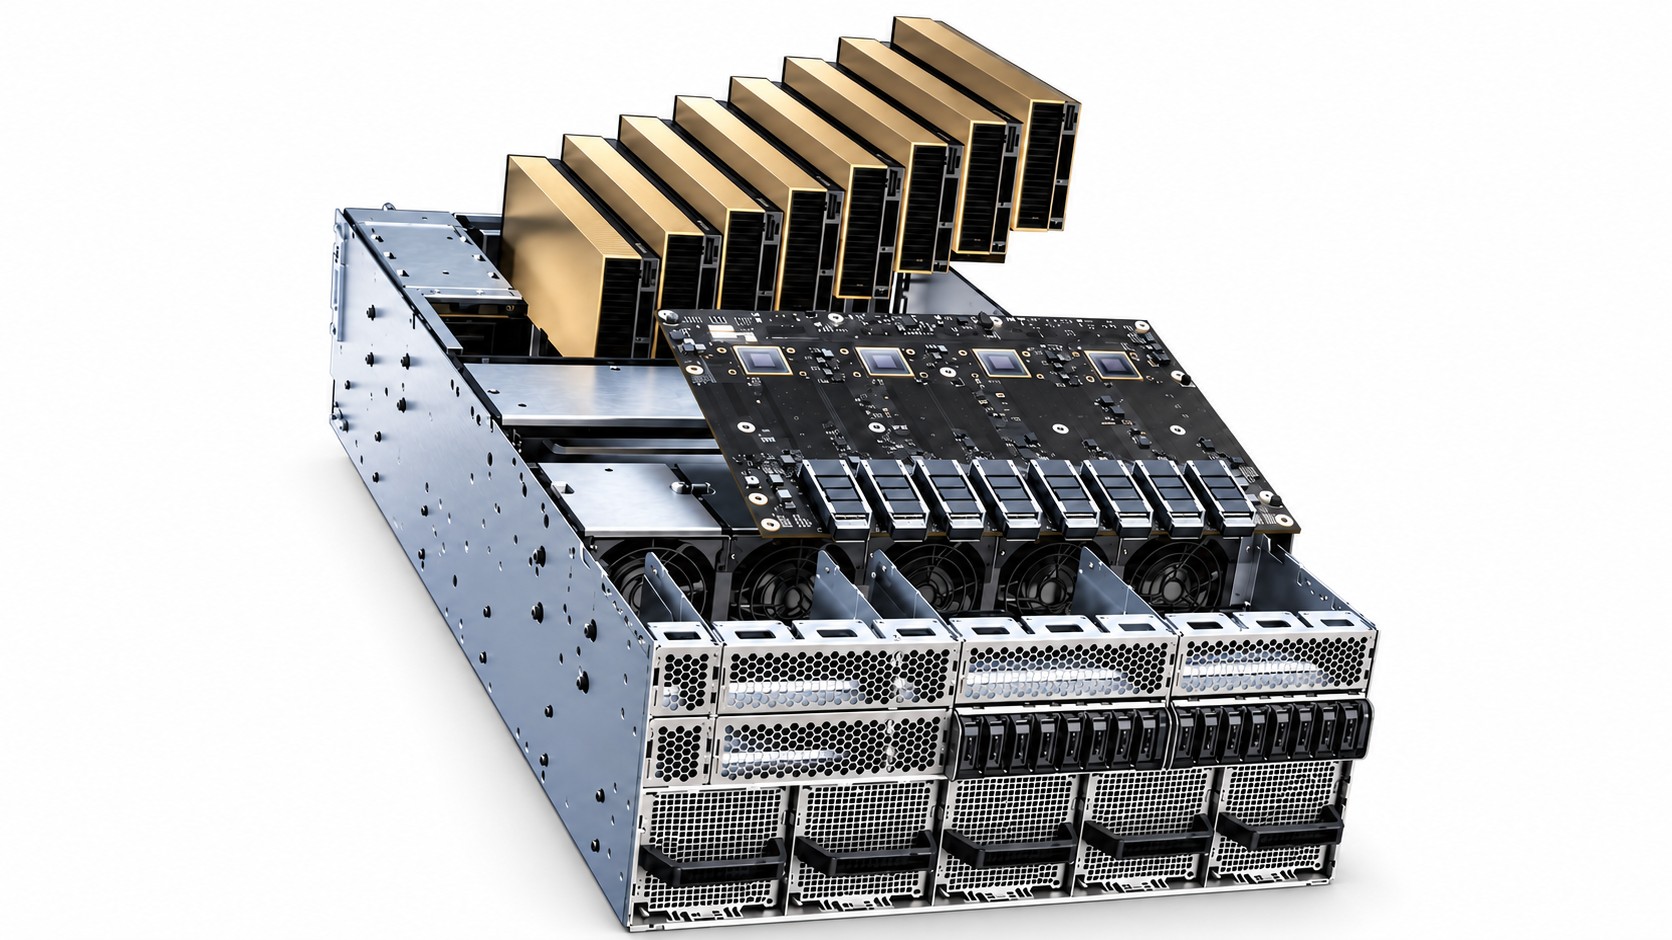
K-SMART AI SERVER — powered by four NVIDIA RTX PRO 6000 Blackwell GPUs
NVIDIA Blackwell RTX PRO 6000 × 4 384GB GPU Memory

Large-scale AI training and inference
in a single server

The NVIDIA RTX PRO 6000 Blackwell Server Edition is a data-center passive GPU designed for multi-GPU server deployments. Each card carries 96GB of GDDR7 ECC memory, giving a four-GPU configuration 384GB of GPU memory. Fine-tuning and inference for large language models, distributed rendering and HPC workloads can all be handled by a single server.

  • Outstanding AI Performance8 PFLOPS at FP8 and 16 PFLOPS at FP4 compute performance
  • Massive Parallel Processing4-GPU parallel configuration accelerates AI/ML workloads
  • Flexible ScalabilityMemory, storage and networking are all expandable
  • Reliable OperationRedundant power and passive cooling design for 24/7 non-stop operation
Specification

Specifications

GPUNVIDIA RTX PRO 6000 Blackwell Server Edition × 496GB GDDR7 (ECC) per card · PCIe 5.0 x16 · Passive cooling
GPU Memory384GB total (96GB × 4)
AI PerformanceFP8 8 PFLOPS / FP4 16 PFLOPSBased on official NVIDIA specifications (per card: FP8 2 PFLOPS · FP4 4 PFLOPS)
CPUIntel® Xeon® Scalable ProcessorsDual-socket support
MemoryDDR5 RDIMM / up to 2TB+
StorageNVMe SSD / U.2 / SATAConfigurable up to 30TB+
Network10 / 25 / 40 / 100GbE support
PowerRedundant Power Supply (80 PLUS Platinum)
Form Factor4U Rackmount Server
CoolingHigh-performance cooling design based on front-to-back chassis airflow

GPU CONFIGURATION PER SERVER

01RTX PRO 6000 · 96GB
02RTX PRO 6000 · 96GB
03RTX PRO 6000 · 96GB
04RTX PRO 6000 · 96GB
384GBTotal GPU Memory
Scalability

Scales to Match Your Needs

Start with one server and grow to a cluster. Configure only what you need for your deployment, then expand later.

ConfigurationGPU CountGPU MemoryPrimary Use
1 ServerRTX PRO 6000 × 4384GBAI training · Inference · R&D
5-Node ClusterRTX PRO 6000 × 201,920GBLarge-scale training · Education institutions · Private cloud
10-Node ClusterRTX PRO 6000 × 403,840GBAI data centers · Supercomputing
1 SERVER

Labs · Departments

Ideal for open-source LLM fine-tuning, RAG-based chatbot development and research model experiments. Recommended for validating at small scale first.

5-NODE CLUSTER

Universities · Institutions

A shared AI platform used by multiple departments and research teams at once, or the backend infrastructure for campus LMS and AI proctoring services.

10-NODE CLUSTER

National · Enterprise Data Centers

A configuration for national education platforms or large-scale AI service operations. We work with you from network and power design onward.

Use Cases

Recommended Applications

The same hardware handles a wide range of AI workloads.

AI Education

The compute foundation for smart campuses, digital textbook platforms and AI tutoring services

AI Research

LLM fine-tuning and inference, multimodal model training, benchmarking and experiment environments

Cloud

On-premises private cloud, virtual workstations (VDI) and AI service infrastructure

Big Data

Large-scale log and sensor data analysis, conversational BI and predictive model operation

Let's scope your deployment together

We propose a configuration that fits your workload and budget, and support you from installation and deployment through operator training and maintenance.
Contact us below for configuration consulting and a quote.

Emailaligo9799@gmail.com Head Office1359-1 Gyoha-ro, Paju-si, Gyeonggi-do, Korea (Bldg. 1 & 2, partial)